
Terms and robots review
A written check of each site's terms, robots.txt rules, and official APIs before any build begins.

For pricing, research, and operations teams: public web data collected on a schedule, cleaned, and delivered where you work, within each site's rules.
10+ hrs
Of copy and paste saved weekly
1
Clean, deduplicated feed per run
How your project runs
Teams we have built for:














The Problem
Manual collection fails quietly. Rows get skipped, prices go stale by lunch, and the one person who knows the routine goes on holiday.
01 · Manual copying
Someone copies prices from 12 sites every morning.
Scheduled scrapers collect the same pages and deliver them automatically.
02 · Broken script
A redesign broke the old script, and nobody noticed.
Layout-change alerts reach your team the same day a scraper fails.
03 · Messy rows
Duplicates, mixed currencies, and blank fields fill the sheet.
Validation rules clean, normalize, and dedupe every run before delivery.
04 · Unclear rules
Nobody knows whether the sites allow collection at all.
We review terms, robots.txt, and official APIs before any build starts.
Every morning, someone opens 12 competitor sites and copies prices into a spreadsheet. By lunch, half of them have changed. An old Python script handled one site until a redesign broke it last month, and nobody noticed for a week. The data that does arrive has duplicates, mixed currencies, and blank fields. Nobody is sure whether the sites allow any of this. Decisions wait on a sheet that's already out of date.
We start with the rules: each site's terms, its robots.txt file, and whether an official API already offers the data. Then we build scheduled scrapers that collect only public pages, at a polite rate, and clean the results into one consistent format. Alerts flag a layout change the same day. Your team gets fresh data delivered, not a morning of copy and paste.
Terms checked first
Site terms, robots.txt rules, and official APIs reviewed before we write a single line of code.
Runs on a schedule
Daily, weekly, or hourly collection where site rules allow, with no one copying by hand.
Clean, deduplicated output
Prices, dates, and currencies normalized, with duplicates removed before the data reaches you.
Our Web Scraping Services Process
You see the terms review, sample data from each site, and the delivery format before any scraper runs on a schedule.
We check each target site's terms of use, robots.txt rules, and whether an official API or data feed exists. You get a go or no-go per site, and we'll say plainly if an API beats scraping.
What's Included
Each project is scoped to your target sites and the data you need. Most include these six parts, from the terms review to monitoring after launch.
Compare Options
A point-and-click tool suits simple pulls, and a freelancer suits a single script. A web scraping company fits once sites, schedules, and data checks multiply.
| Feature | DeveloperLookBest fit | Scraping tool | Freelancer |
|---|---|---|---|
| Terms review | Every site, before building | Left to you | Rarely done |
| JavaScript pages | Playwright where needed | Often supported | Depends on the person |
| Data cleaning | Validated and deduplicated | Basic exports | Varies by person |
| Scheduling | Hourly, daily, or weekly | Built-in schedules | Manual reruns |
| When sites change | Same-day alerts and fixes | You fix the recipe | If they're available |
| Setup speed | 1 to 6 weeks | Same day for simple sites | Fast for one script |
| Ownership | Code in your repository | Recipes in the vendor's tool | Script, if handed over |
| Cost | Fixed price from $750 | Monthly subscription | Hourly, varies |
Projects We've Built
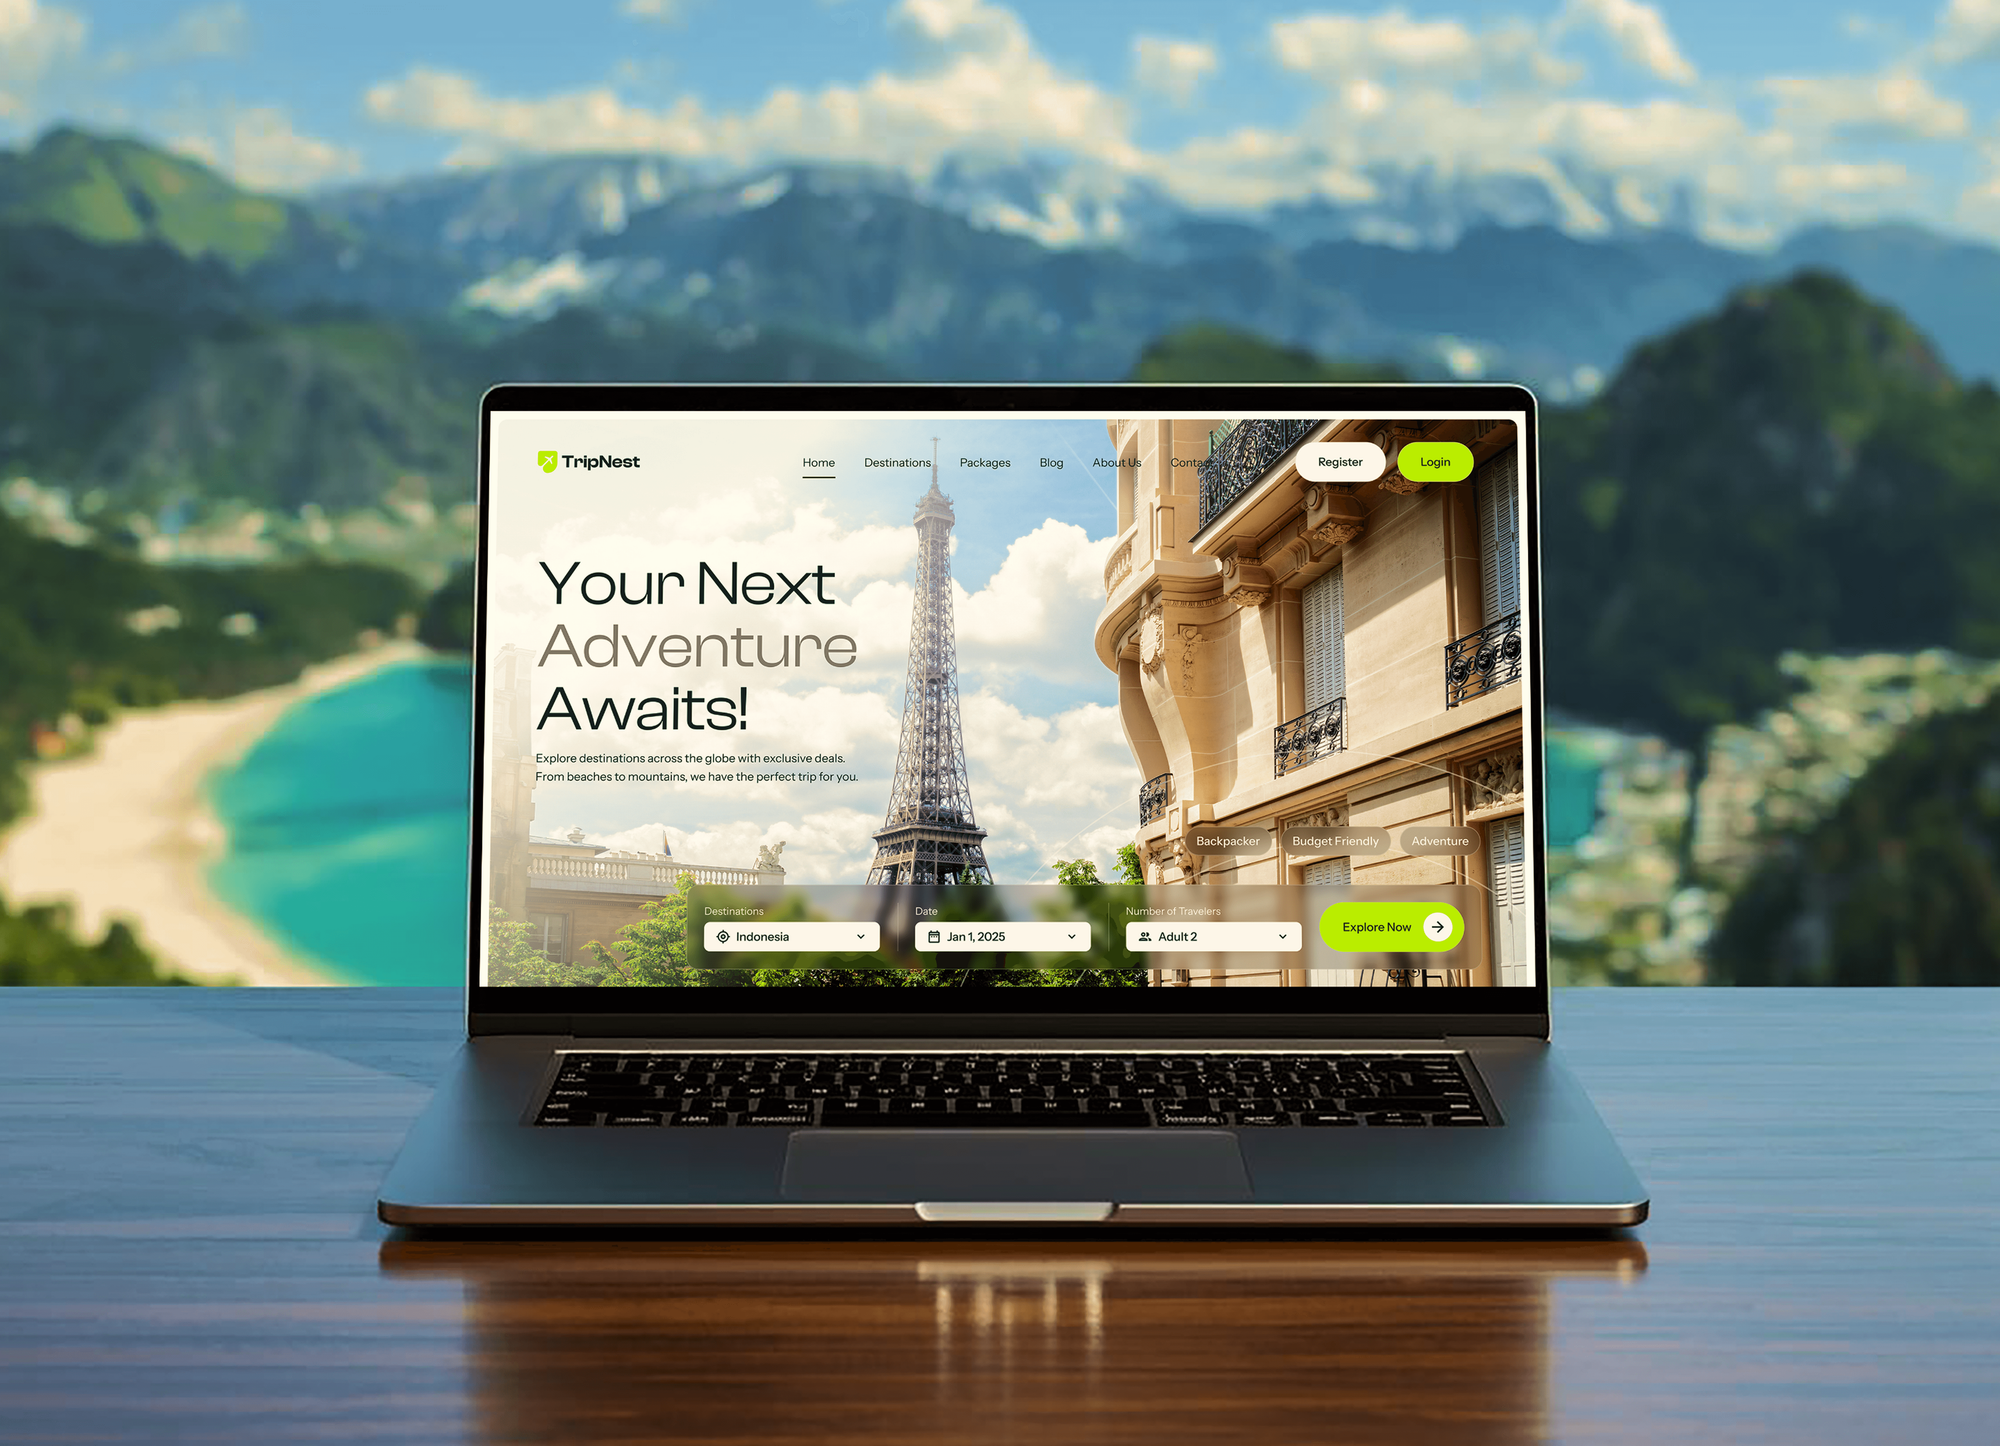
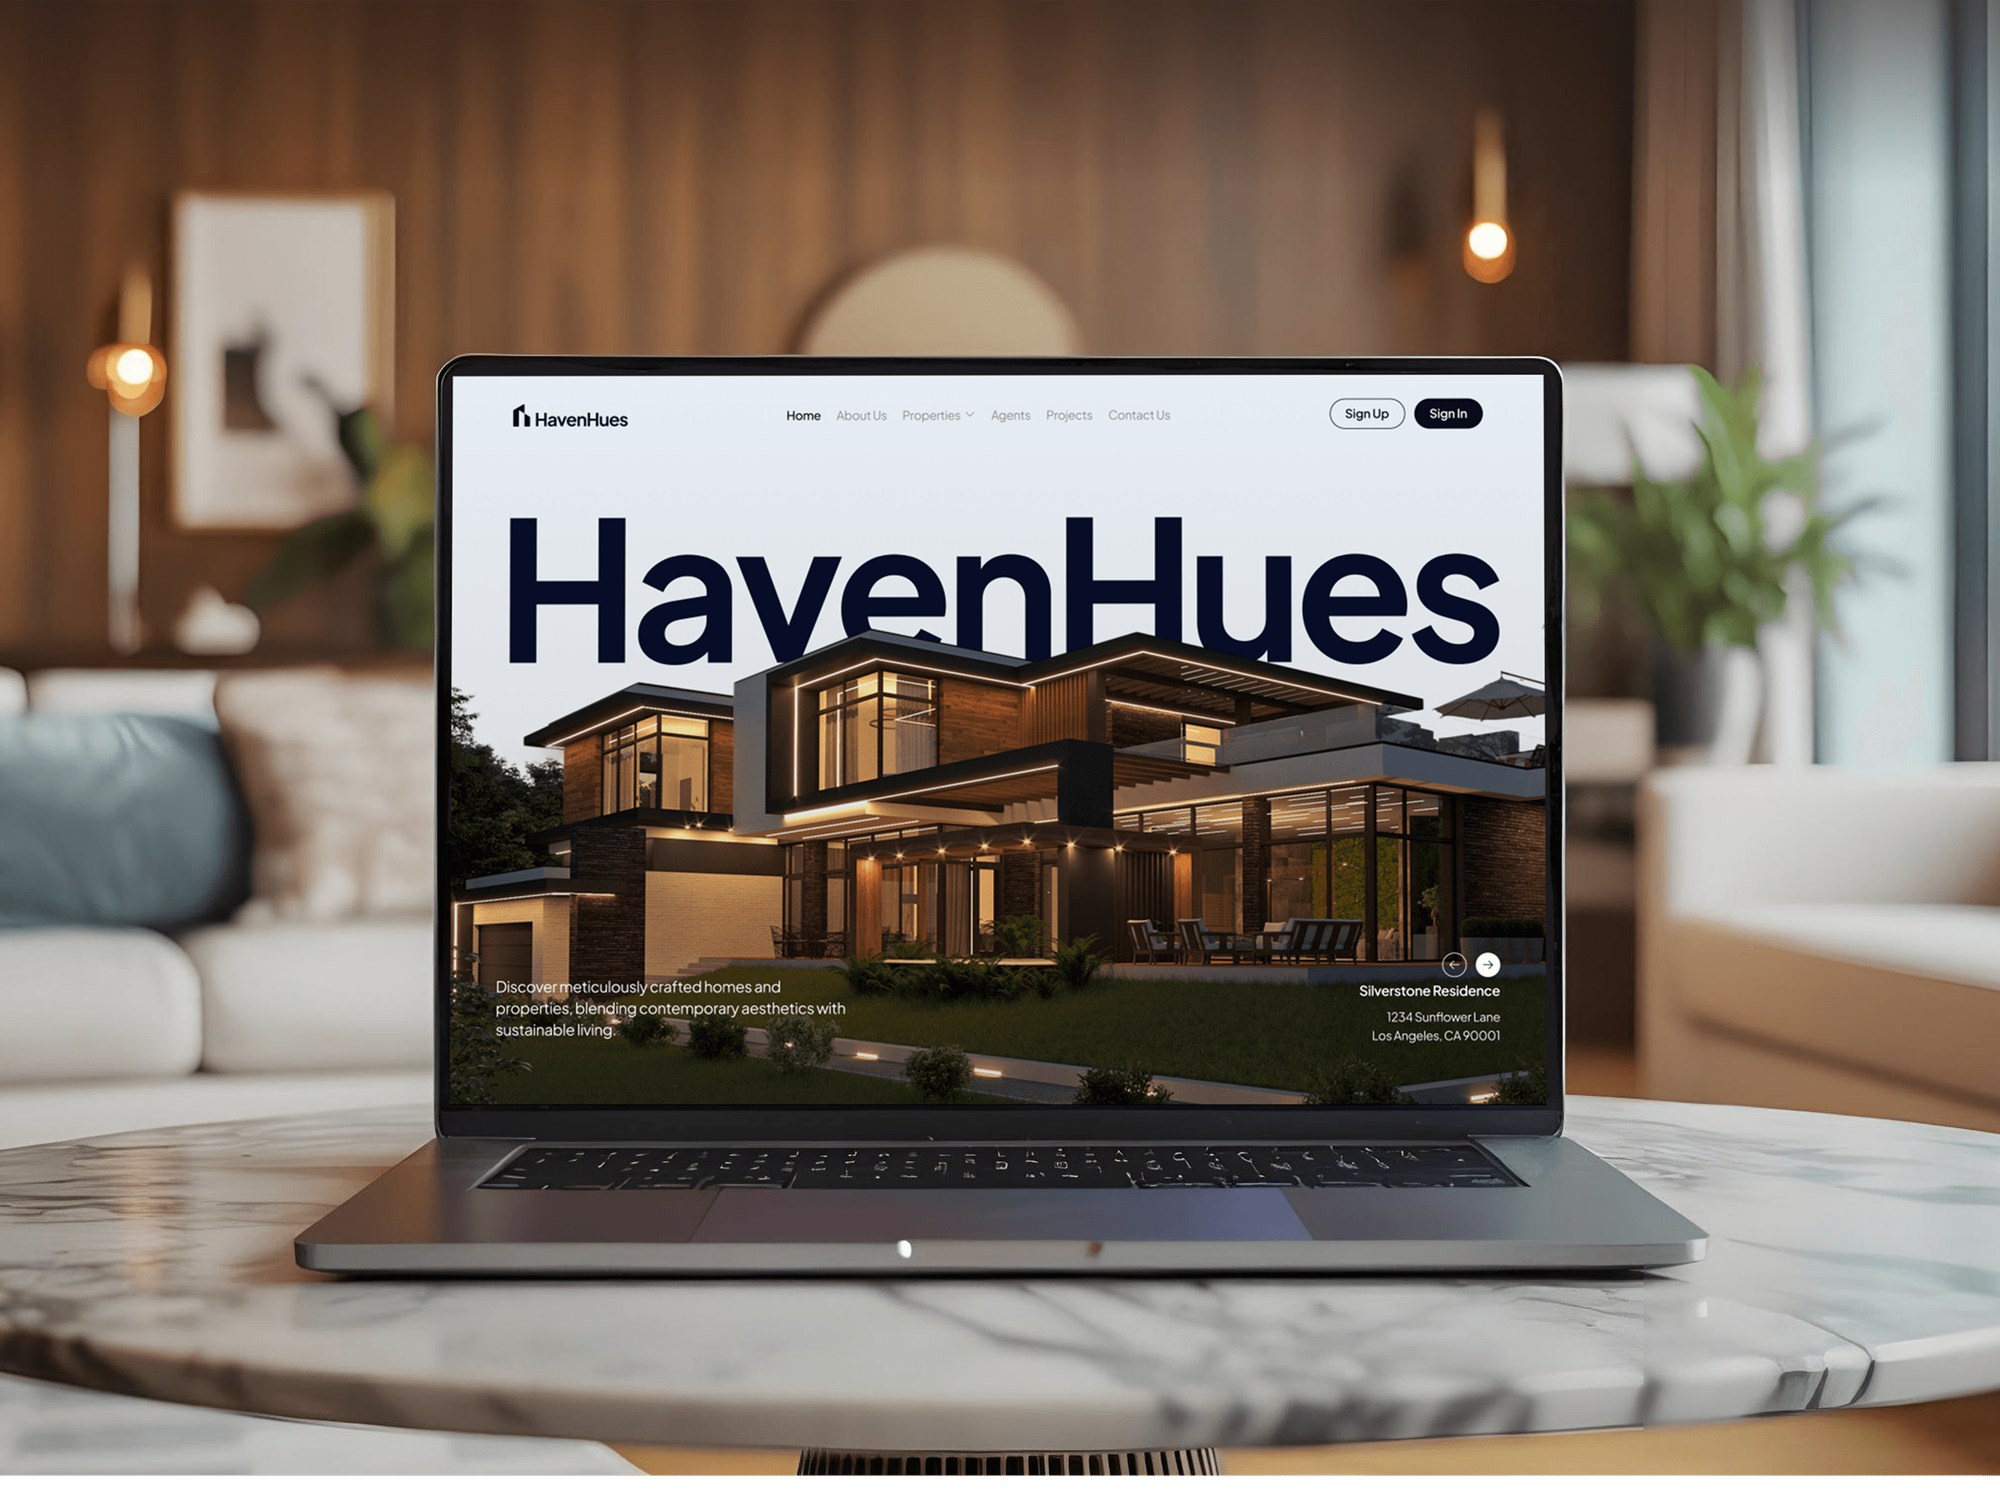
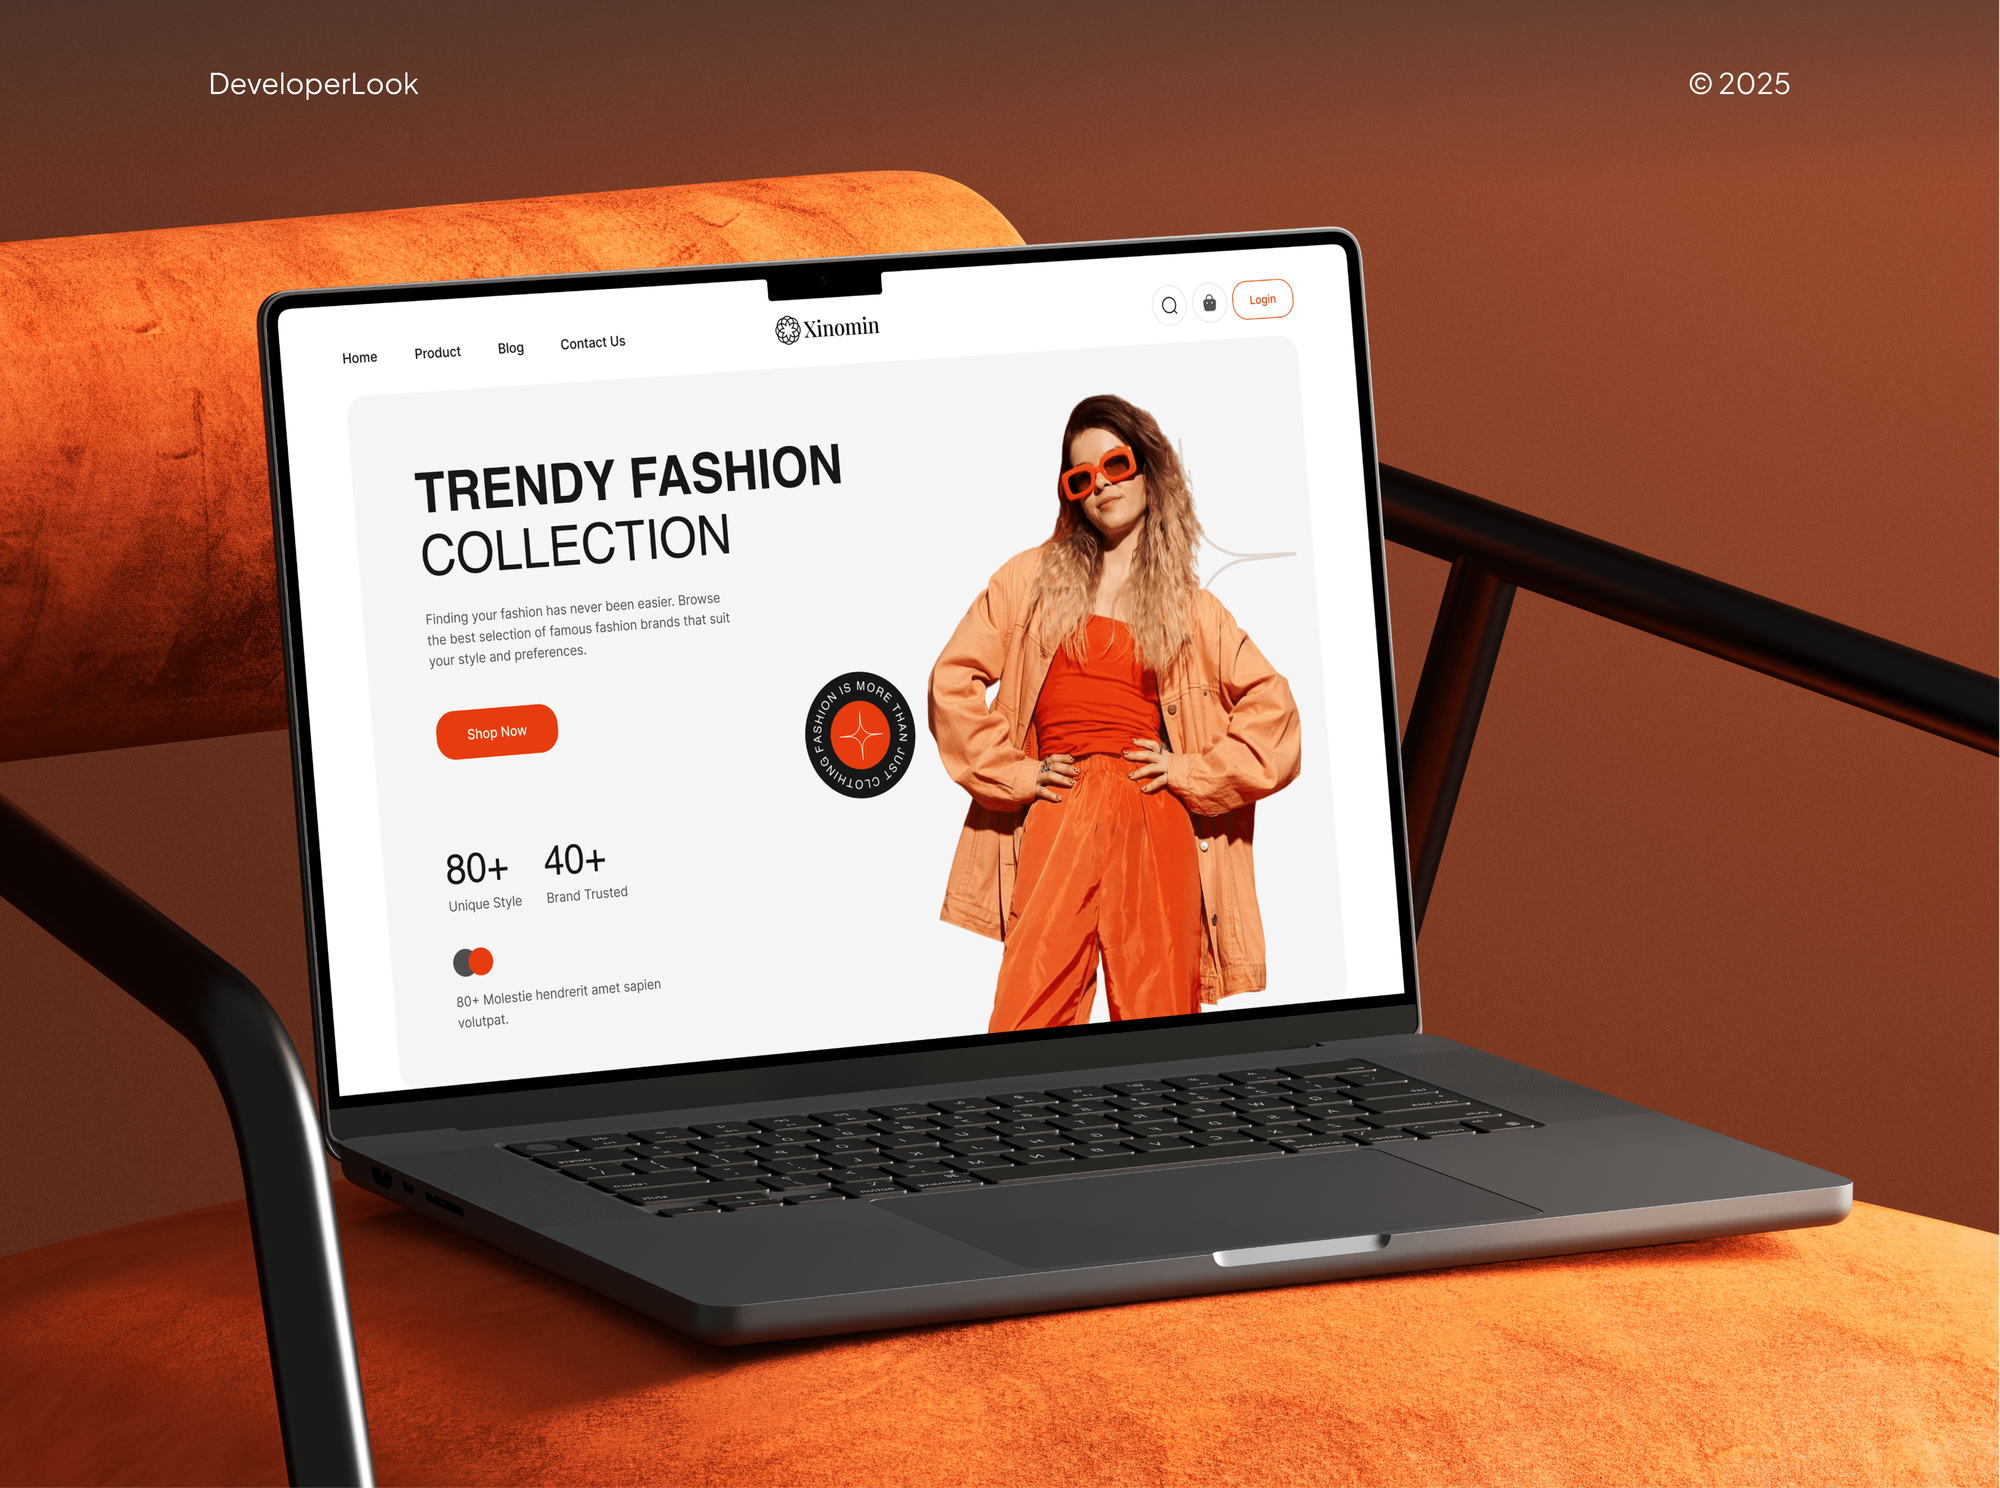
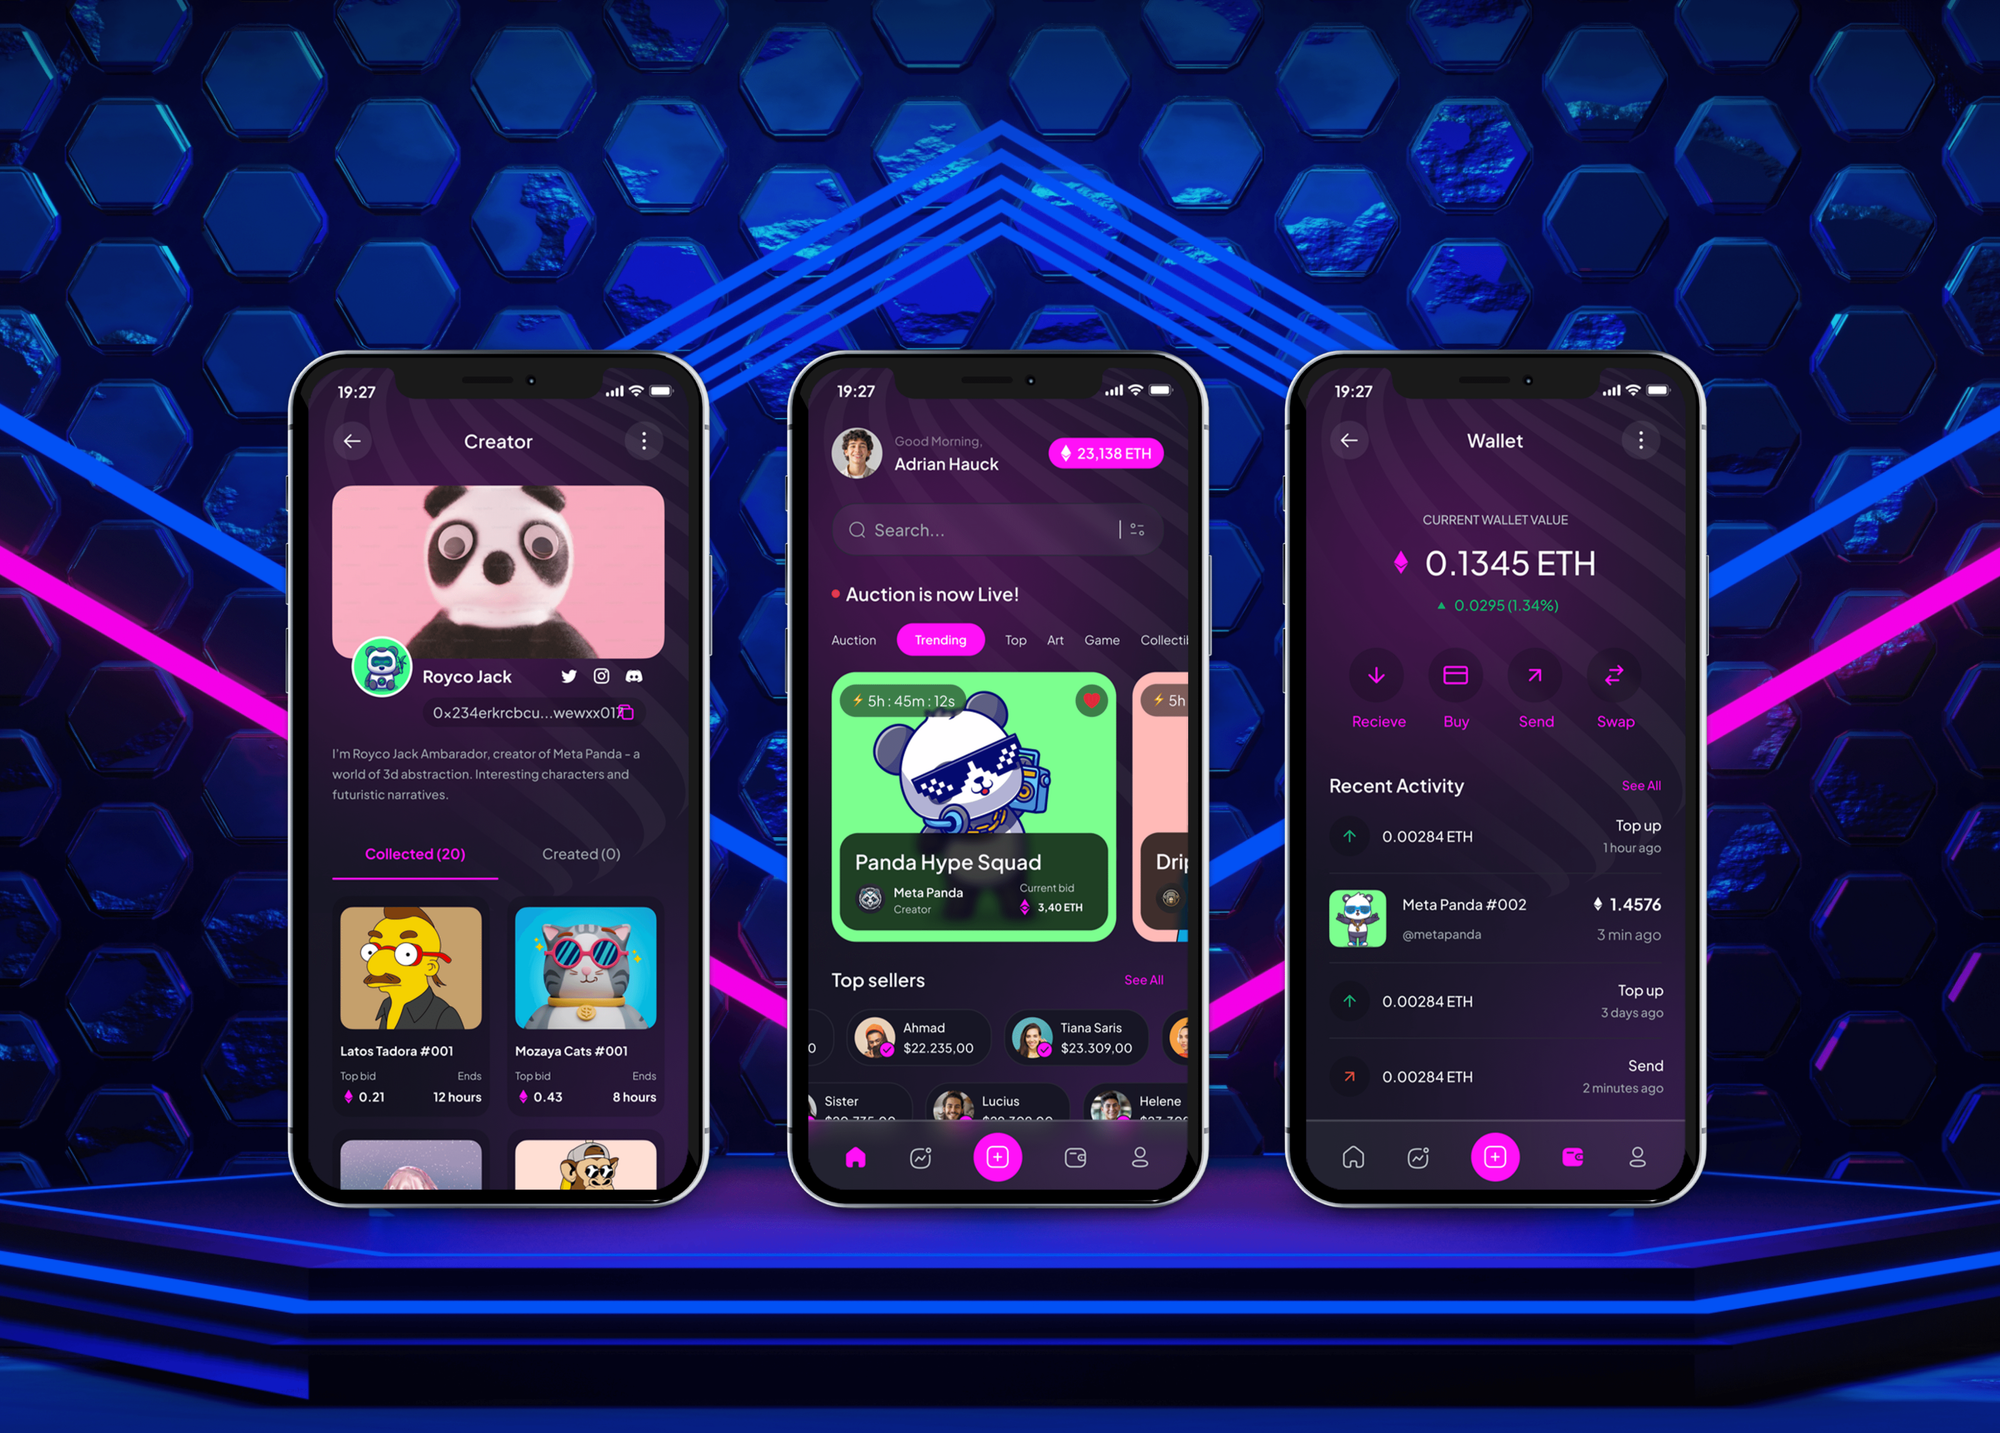
Travel, real estate, store, and trading products from our portfolio. None was a scraping project, but each shows the kind of listings and prices teams often need to track.
What Our Clients Say
Feedback from teams we have built websites, stores, and web apps for.
We had a pretty specific idea of what we wanted our website to become, but I wasn’t sure how easily we could explain all of it to a development team. There were quite a few moving parts, and we were working toward a deadline, so I expected a few things to get lost along the way. That never really happened. They understood what we were trying to achieve, kept us updated throughout the process, and got everything ready within the agreed timeline. The final site feels much easier to navigate, works beautifully on mobile, and is noticeably smoother for our customers. It was a huge relief seeing the original idea actually turn into the website we had in mind.
The mobile experience is probably my favourite part of the new site. We had spent a lot of time making sure the desktop version looked right, and the team kept pushing us to think about how everything would actually feel on a phone too. They were right. The navigation is clean, the interactions feel natural, and everything we’ve tested so far works exactly as it should. They also went through the links, forms, integrations, and other details more than once before launch, which I really appreciated. And even after going live, we could still reach out when something came up. The whole process felt friendly, organised, and surprisingly straightforward.
What I appreciate most is that the website is actually easy for us to manage now. We can update content ourselves instead of sending a developer a message every time we need to change something small. They also paid attention to the technical SEO side, which mattered to us because we didn’t want a new website to create problems for the traffic we already had. I’ve probably asked more questions than I should have since launch, but every question has been handled patiently and without any fuss. The team is easy to work with, they explain things clearly, and when we need something changed, they focus on getting it done rather than making the process complicated.
1,250+
Projects shipped
10+
Years of experience
Top 3%
Upwork Top Rated Plus
5 stars
Average review score

Want results like these?
Tell us what you are building. You get a reply within 24 hours on business days, then a written estimate.
Work Culture
Careless scraping can break a site's rules or hurt your reputation. These habits keep collection polite, legal questions visible, and your data reliable.
We check for an official API, data feed, or license before writing a scraper. If one covers your need, we'll tell you before we quote.
Scrapers keep a slow, steady request rate and run at quiet hours where possible. Target sites stay fast for their own visitors.
We collect what any visitor can see without logging in, and skip anything behind a login or CAPTCHA. That keeps your project clear of access disputes.
Names, emails, and other personal details stay out of feeds unless your use has a lawful basis under laws like GDPR or CCPA. We strip what you don't need.
Every run stores the raw pages it read. Any row can be traced back to its source page and the date it was collected.
Scrapers, schedules, and data live in your accounts from the first run. You can move them in-house later without starting over.
Overview
DeveloperLook provides web scraping services for teams that copy data from websites by hand. We review each site's terms and robots.txt rules, build scheduled scrapers for public pages, clean the results, and deliver them to your sheet or database. Projects start at $750, take 1 to 6 weeks, and the code is yours.
DEVELOPERLOOK
Project facts · Web Scraping Services
Reviewed 8 Oct 2026 by Saimul Islam
Good fit
Ecommerce teams tracking competitor prices
Your team checks competitor prices and stock by hand every morning, and by the time the sheet is done, prices have changed.
Research and analytics teams
You need a dataset from public websites for a model or report, and copying it by hand would take your team weeks.
Platforms aggregating public listings
Your platform shows listings gathered from public sources, and you need data scraping services that respect each site's terms.
Operations teams watching public records
You monitor public notices, permits, or tenders across many government sites, and missing one costs you a deal.
Teams with a broken in-house scraper
Your developer's script stopped working after a site redesign, and nobody has time to fix it or keep watching it.
Not a fit
Data behind a login
You need data behind a login, a paywall, or a CAPTCHA. We collect public data only, so an official API or a data license is the better route.
Site has an official API
The site already offers an official data API or feed. Our API Integration Services page connects to it, which is more stable than scraping.
Feed needs a warehouse
You need scraped data joined with sales, CRM, and finance data in one warehouse. Our Data Engineering Services page builds that platform around the feed.
One small pull, under $750
You need a few hundred rows once, and your budget is under $750. A browser extension or a manual export will do, and we'll tell you before we quote.
Not sure we're the right fit?
Book a free call or message us. We'll tell you honestly whether we're the right team.
Pricing
These are starting points in USD. Your final price depends on the number of sites and page types, how often data must refresh, and where it's delivered, and you get a fixed proposal after a free terms review.
For one public website with one page type, collected on a regular schedule.
$750one-time, USD
For teams tracking several sites who need the data in a database.
$2,100one-time, USD
For businesses that rely on fresh public web data every single day.
$4,600one-time, USD
For Agencies
You own the client relationship. We build and run the data collection behind it: terms reviews, scrapers, cleaning, and scheduled delivery. Fixed quotes protect your margin, and every feed arrives in a format your client's tools already read.
White label: your client only ever sees your brand
Send the target sites, the fields your client needs, and the delivery format.
You get a terms review, sample rows, and a fixed quote for each site.
Scheduled, cleaned data delivered under your agency's brand, with alerts on failures.
Your brand on every report and feed, and we stay out of client calls.
Each site and feed priced upfront, so your margin holds.
A terms and robots.txt summary for each site that you can share.
Layout-change alerts reach you before your client notices missing data.
The Right Technology for Your Project
We use open-source Python tools for collection, headless browsers only where pages need them, and your own cloud account for scheduling.
 Python
 PostgreSQL
 Docker
 AWS
 Google Cloud
 Google Sheets
 Slack
 Node.js
FAQ
Straight answers on legality, Amazon and Zillow rules, costs, and how our web data scraping services work.
Saimul IslamFounder & CEO, DeveloperLookStill have questions?
Send a message or book a call with the team.
Web scraping is using software to read web pages and pull out specific data, such as prices, product names, or listing details. A scraper loads a page, finds the fields it needs in the HTML, and saves them in a structured format. Search engines, price comparison sites, and researchers all rely on it.
A web scraper requests a page, reads its HTML, and extracts fields using selectors, much like your browser finds an element. Pages that load data with JavaScript need a headless browser such as Playwright. The scraper then cleans the data and repeats the process on a schedule.
A website scraping service from DeveloperLook starts at $750 for one public site and one page type on a schedule. Feeds from up to 5 sites with change detection start at $2,100. Pipelines covering up to 15 sites with hourly runs start at $4,600. Cloud hosting costs stay on your own account.
One site usually takes 1 to 2 weeks, and a multi-site feed takes 3 to 6 weeks. Sites that load data with JavaScript or change layouts often take longer, because each needs its own handling and tests. The terms review in the first days can also rule a site out.
Collecting publicly available data is often legal, but it depends on the site's terms, the type of data, and where you operate. Copyright, contract terms, and privacy laws such as GDPR can still apply. This isn't legal advice, so check your use case with a lawyer, and we document each site's rules for that conversation.
Scraping public pages is unlikely to violate the federal Computer Fraud and Abuse Act, the Ninth Circuit said in its 2022 hiQ v. LinkedIn ruling. A later ruling in the same case found hiQ breached LinkedIn's user agreement, so site terms still matter. Copyright and state privacy laws apply too, and this isn't legal advice.
Web scraping is used for price and stock monitoring, market research, real estate and job listings, public records tracking, and datasets for analysis. Ecommerce teams watch competitor catalogs, and researchers collect public data at a scale manual copying can't reach. Each use should stay within the source site's rules.
Web scraping is ethical when you collect public data, follow the site's terms and robots.txt rules, and don't overload its servers. Problems start when scrapers take personal data without a lawful basis, copy content to republish it, or work around blocks. We follow the first set of rules and decline the second kind of work.
No. Amazon's Conditions of Use exclude data mining, robots, and similar data gathering and extraction tools from the license to use its site. For product data, Amazon offers official routes, such as the Selling Partner API for sellers and the Product Advertising API for Associates. We use those instead of scraping Amazon pages.
No. Zillow's terms of use prohibit automated queries and scraping without its written permission. Listing data reaches developers through Bridge Interactive, a Zillow Group platform that needs approval and often an MLS agreement. For real estate projects, we connect to approved feeds instead of scraping Zillow pages.
Saimul IslamFounder & CEO, DeveloperLookStill have questions?
Send a message or book a call with the team.
Free 30-min callGoogle Meet
Book a call
In 30 minutes on Google Meet we walk you through how we would build it, how long it takes and what it costs. Then you get a written estimate.
Calendar not showing? Book on cal.com or send a brief.