
Source ingestion
Connectors and Python jobs for databases, SaaS APIs, and files, loading incrementally so production systems stay fast.

For companies pulling numbers from Stripe, CRMs, and production databases: one tested warehouse, and pipelines that alert you when a load fails.
1
Warehouse for every source
24/7
Pipeline failure alerts
How your project runs
Teams we have built for:














The Problem
Data problems show up in meetings. Finance, sales, and product each bring a different number, and nobody can say which pipeline produced it.
01 · Many sources
Revenue lives in Stripe, HubSpot, and a replica that disagree.
Every source loads into one warehouse, with the raw history kept.
02 · Laptop scripts
A Python script on one laptop loads the warehouse.
Scheduled pipelines run in Airflow, versioned in your own GitHub account.
03 · Mystery tables
Nobody knows which orders table the board deck uses.
Documented dbt models with tests replace orders_final_v2 and its cousins.
04 · Silent breaks
A new source column breaks the load without warning.
Failed runs alert your team the same day, naming the step that broke.
It's Monday, and three people pulled revenue from three places. Finance used the Stripe export, sales used HubSpot, and the product team queried a database replica that failed overnight. A Python script on someone's laptop loads the warehouse, when it runs. Tables carry names like orders_final_v2, and nobody knows which one the board deck uses. When a source adds a column, the load breaks quietly. The dashboard then shows last Thursday's numbers as today's, and each new question costs a week of manual joins.
We start by mapping every source, the questions the data must answer, and who owns each metric. Then we build ELT pipelines into one warehouse, model the tables in dbt with tests on every key column, and schedule runs in Airflow with alerts on failure. Your teams query one set of documented tables. Numbers get settled in the pipeline, not argued over in the meeting.
One warehouse, every source
Stripe, HubSpot, production databases, and spreadsheets land in one warehouse with their full history kept.
Tests on every key table
dbt tests check uniqueness, nulls, and accepted values before bad rows reach a report.
Alerts when a load fails
A failed or late pipeline run posts to Slack or email with the step that broke.
Our Data Engineering Services Process
You see the source map, the warehouse design, and test results from a real backfill before any pipeline goes live.
We list every system that holds data you report on: databases, SaaS tools, files, and APIs. We check access, volume, and how often each one changes. You get a source map and an honest view of whether you need us at all.
What's Included
Every engagement is scoped to your sources and questions. Most combine these six parts, from ingestion to the documentation your team keeps after launch.
Compare Options
An ELT tool suits standard connectors, and an in-house hire suits ongoing work. Here's where each one fits as your sources and questions multiply.
| Feature | DeveloperLookBest fit | In-house hire | ELT tool |
|---|---|---|---|
| Time to first pipeline | 3 to 5 weeks | After hiring and onboarding | Hours for standard connectors |
| Source coverage | Any database, API, or file | Whatever they can build | The vendor's connector list |
| Transformations | Tested dbt models | Depends on the hire | Basic or none |
| Data testing | Tests on every key model | When time allows | Sync status only |
| Failure alerts | Slack or email, same day | Built up over time | Built-in sync alerts |
| Business context | Runbook and handover | Deep, day to day | Vendor support desk |
| Ownership | Your repo and accounts | Yours, while they stay | Vendor-hosted connectors |
| Cost | Fixed price from $1,400 | Full-time salary | Monthly fees by volume |
Projects We've Built
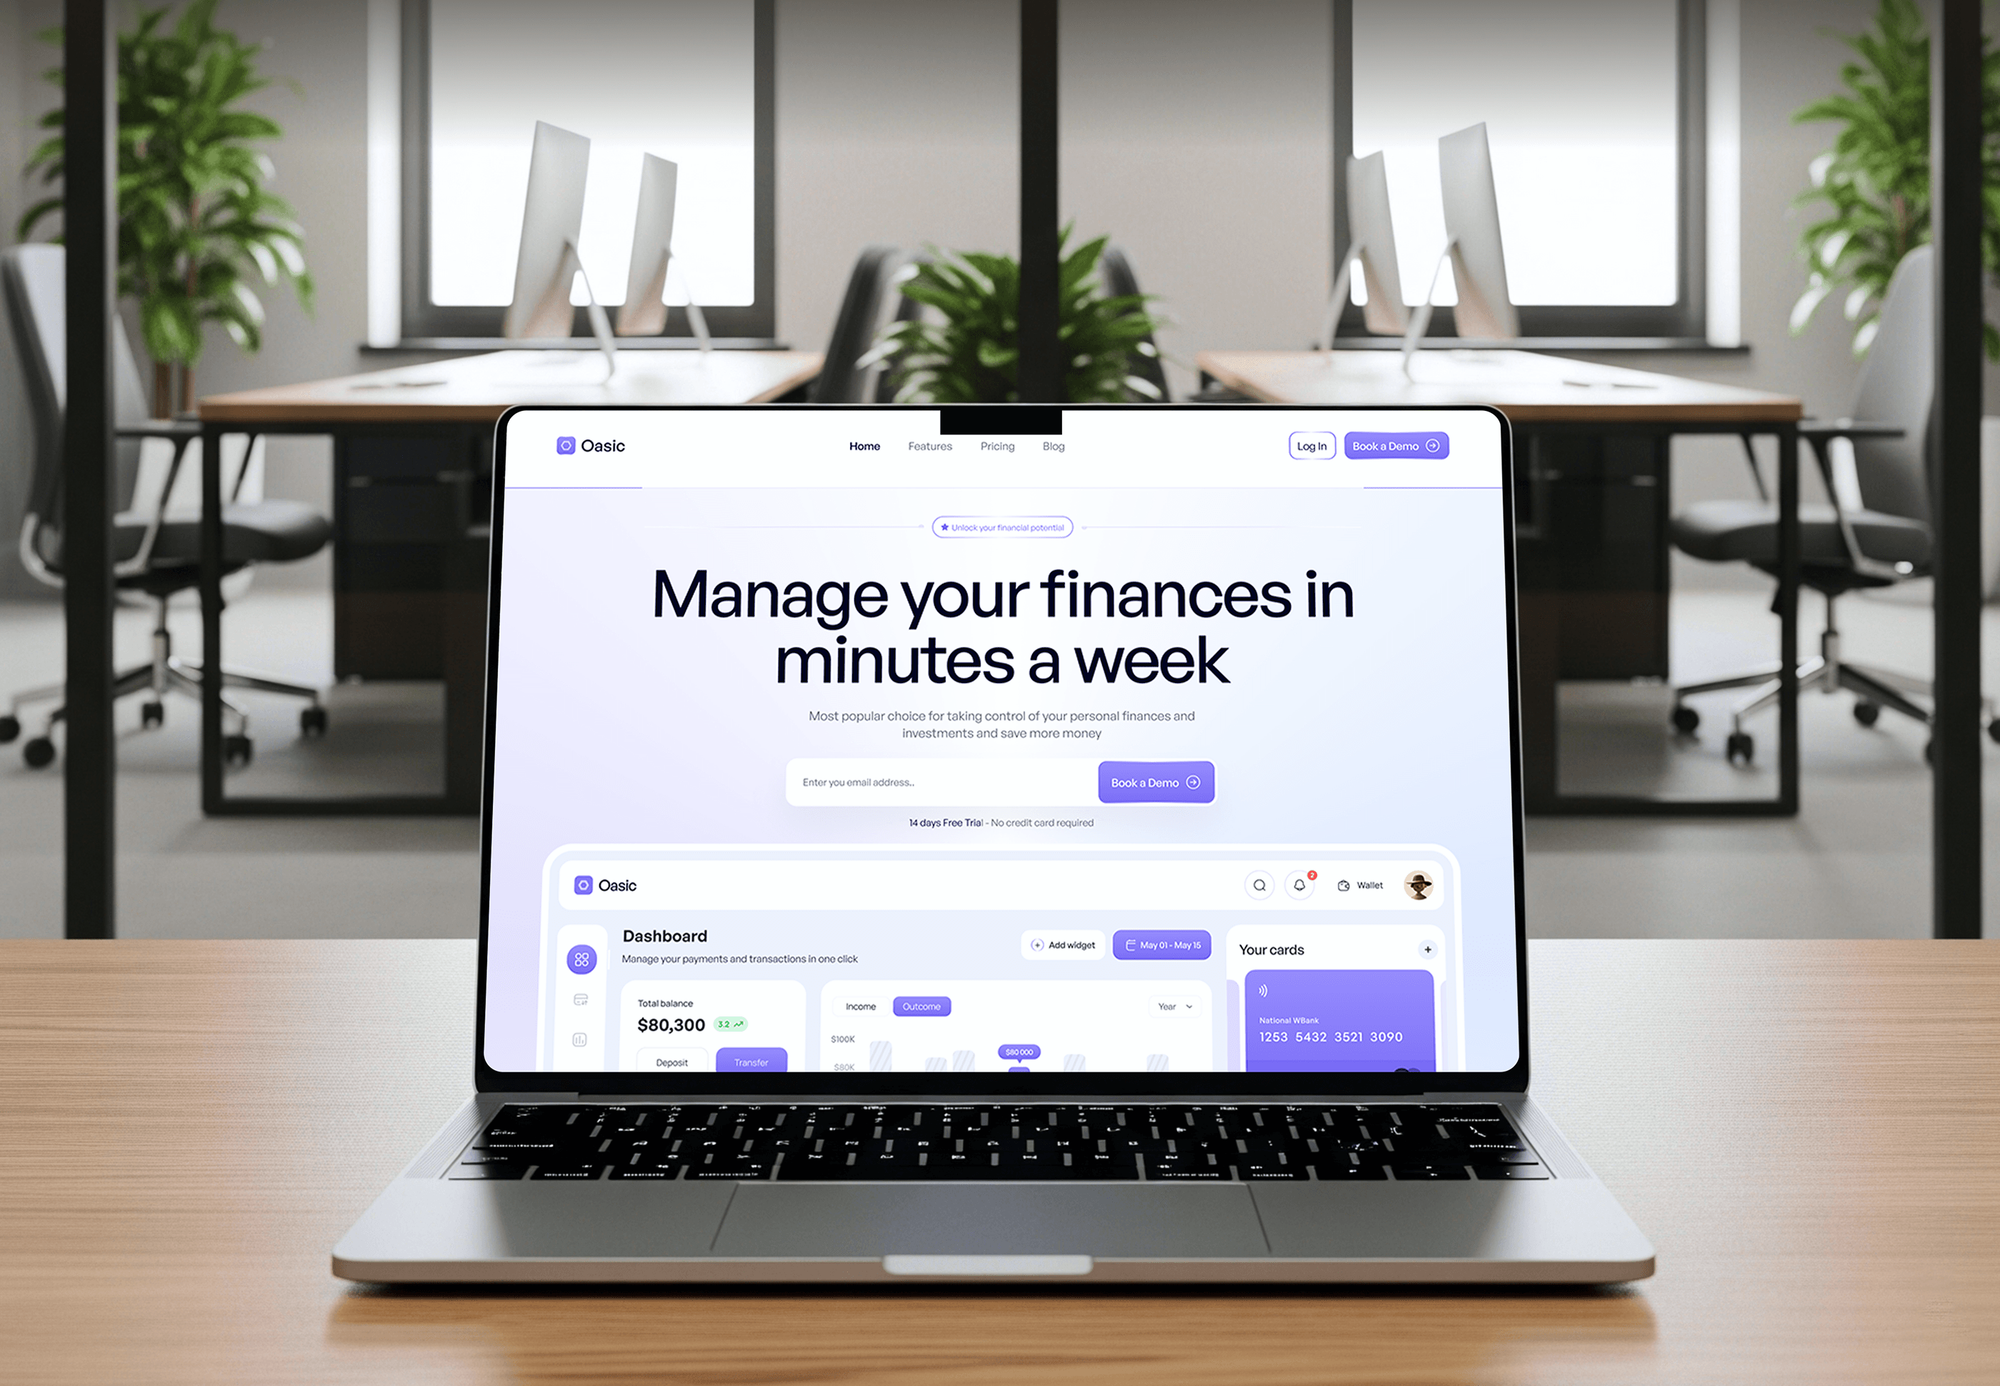
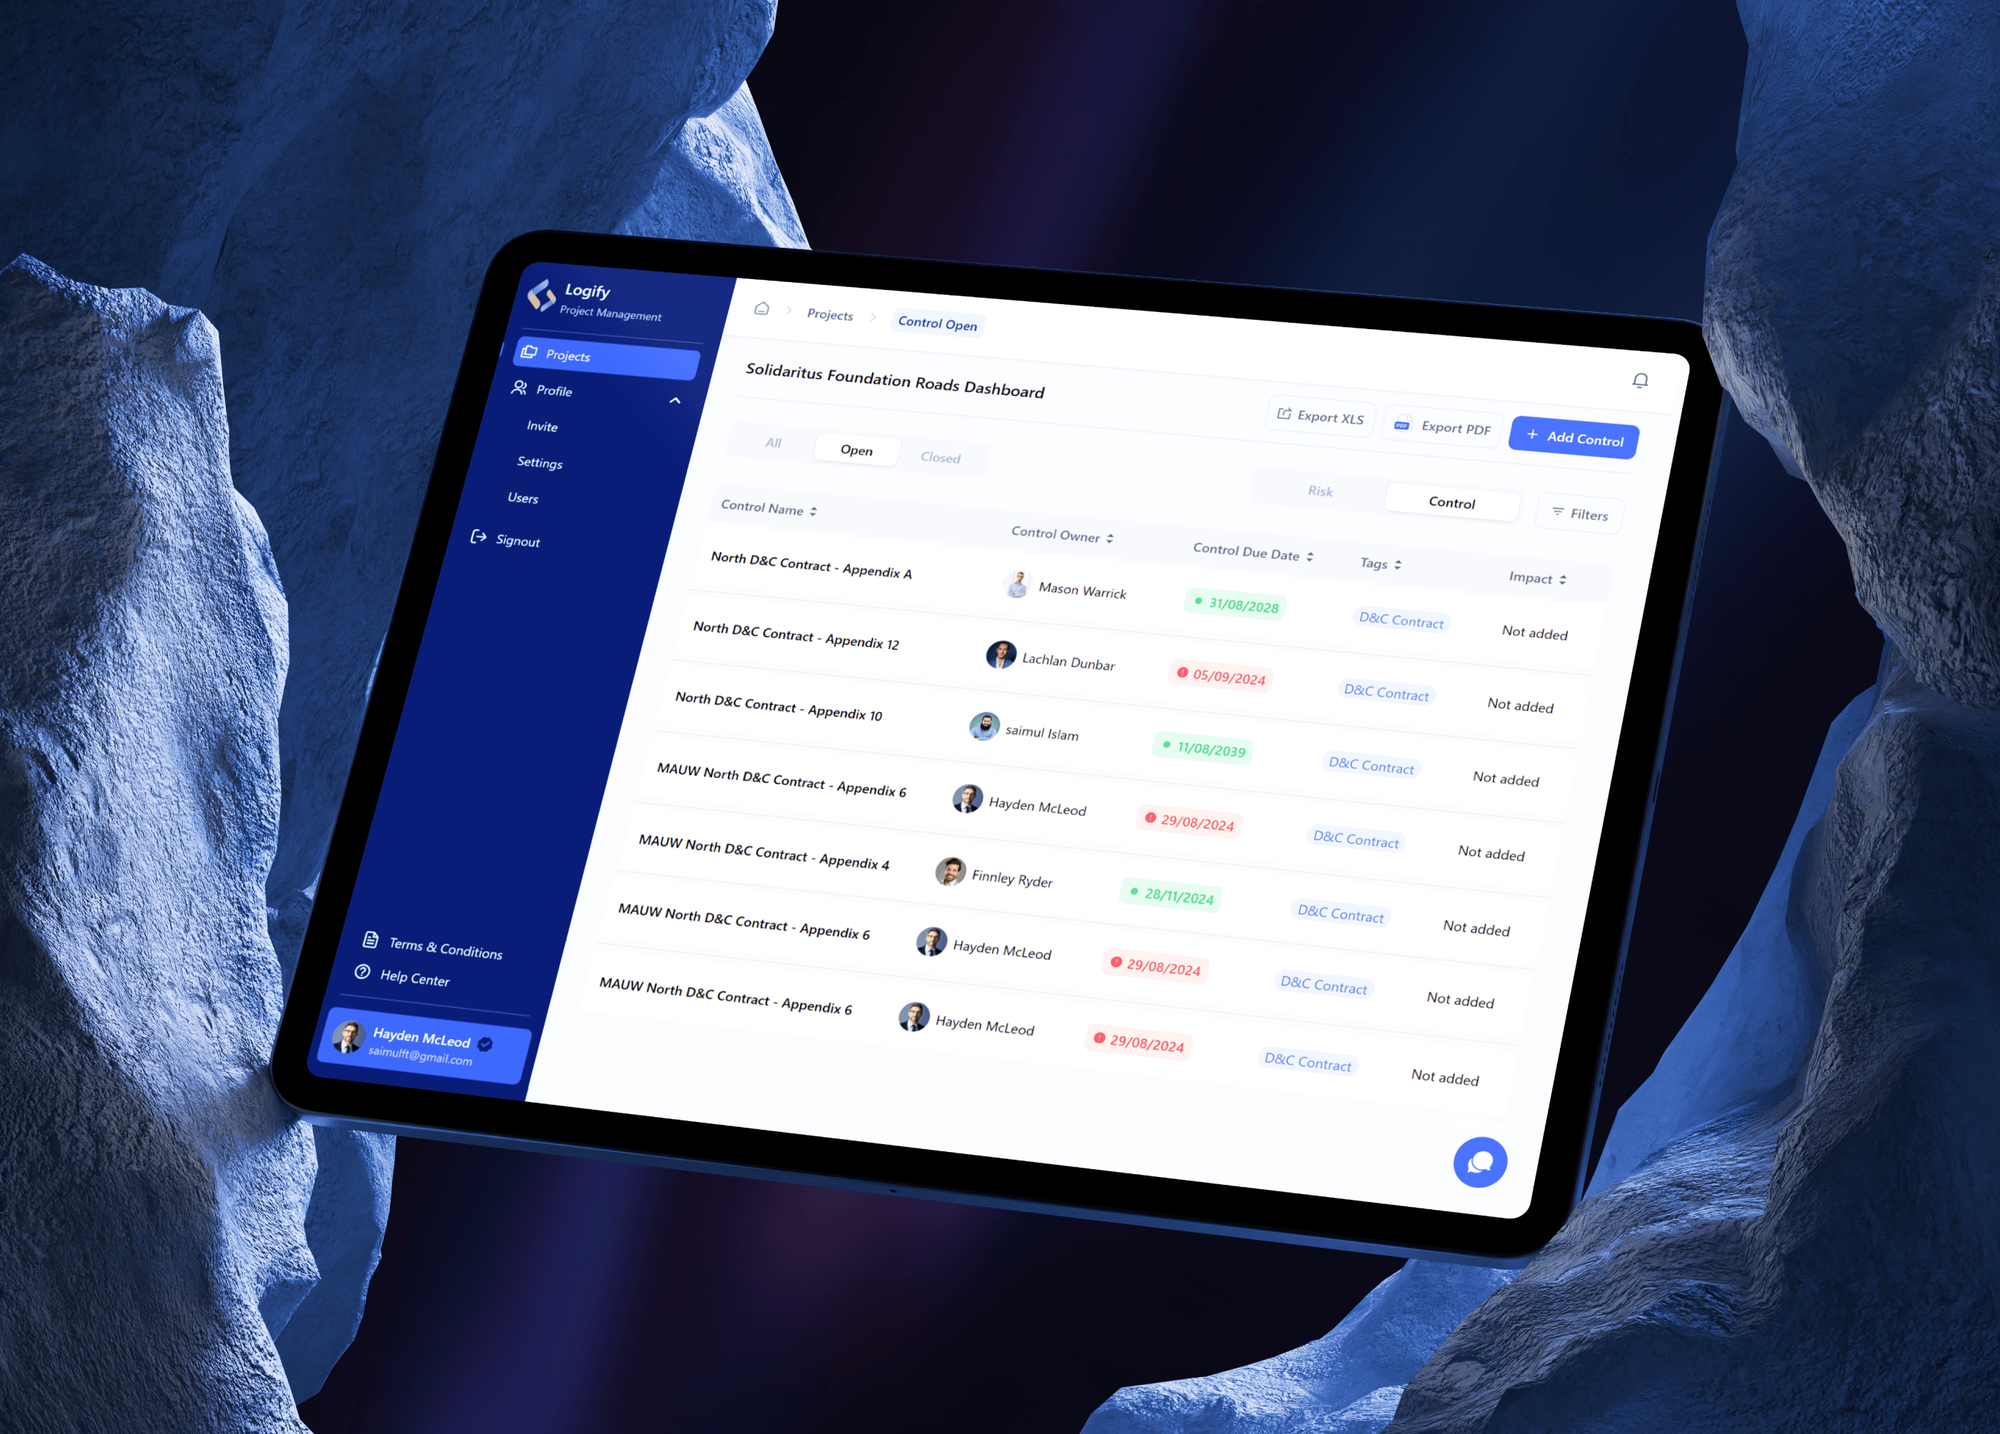
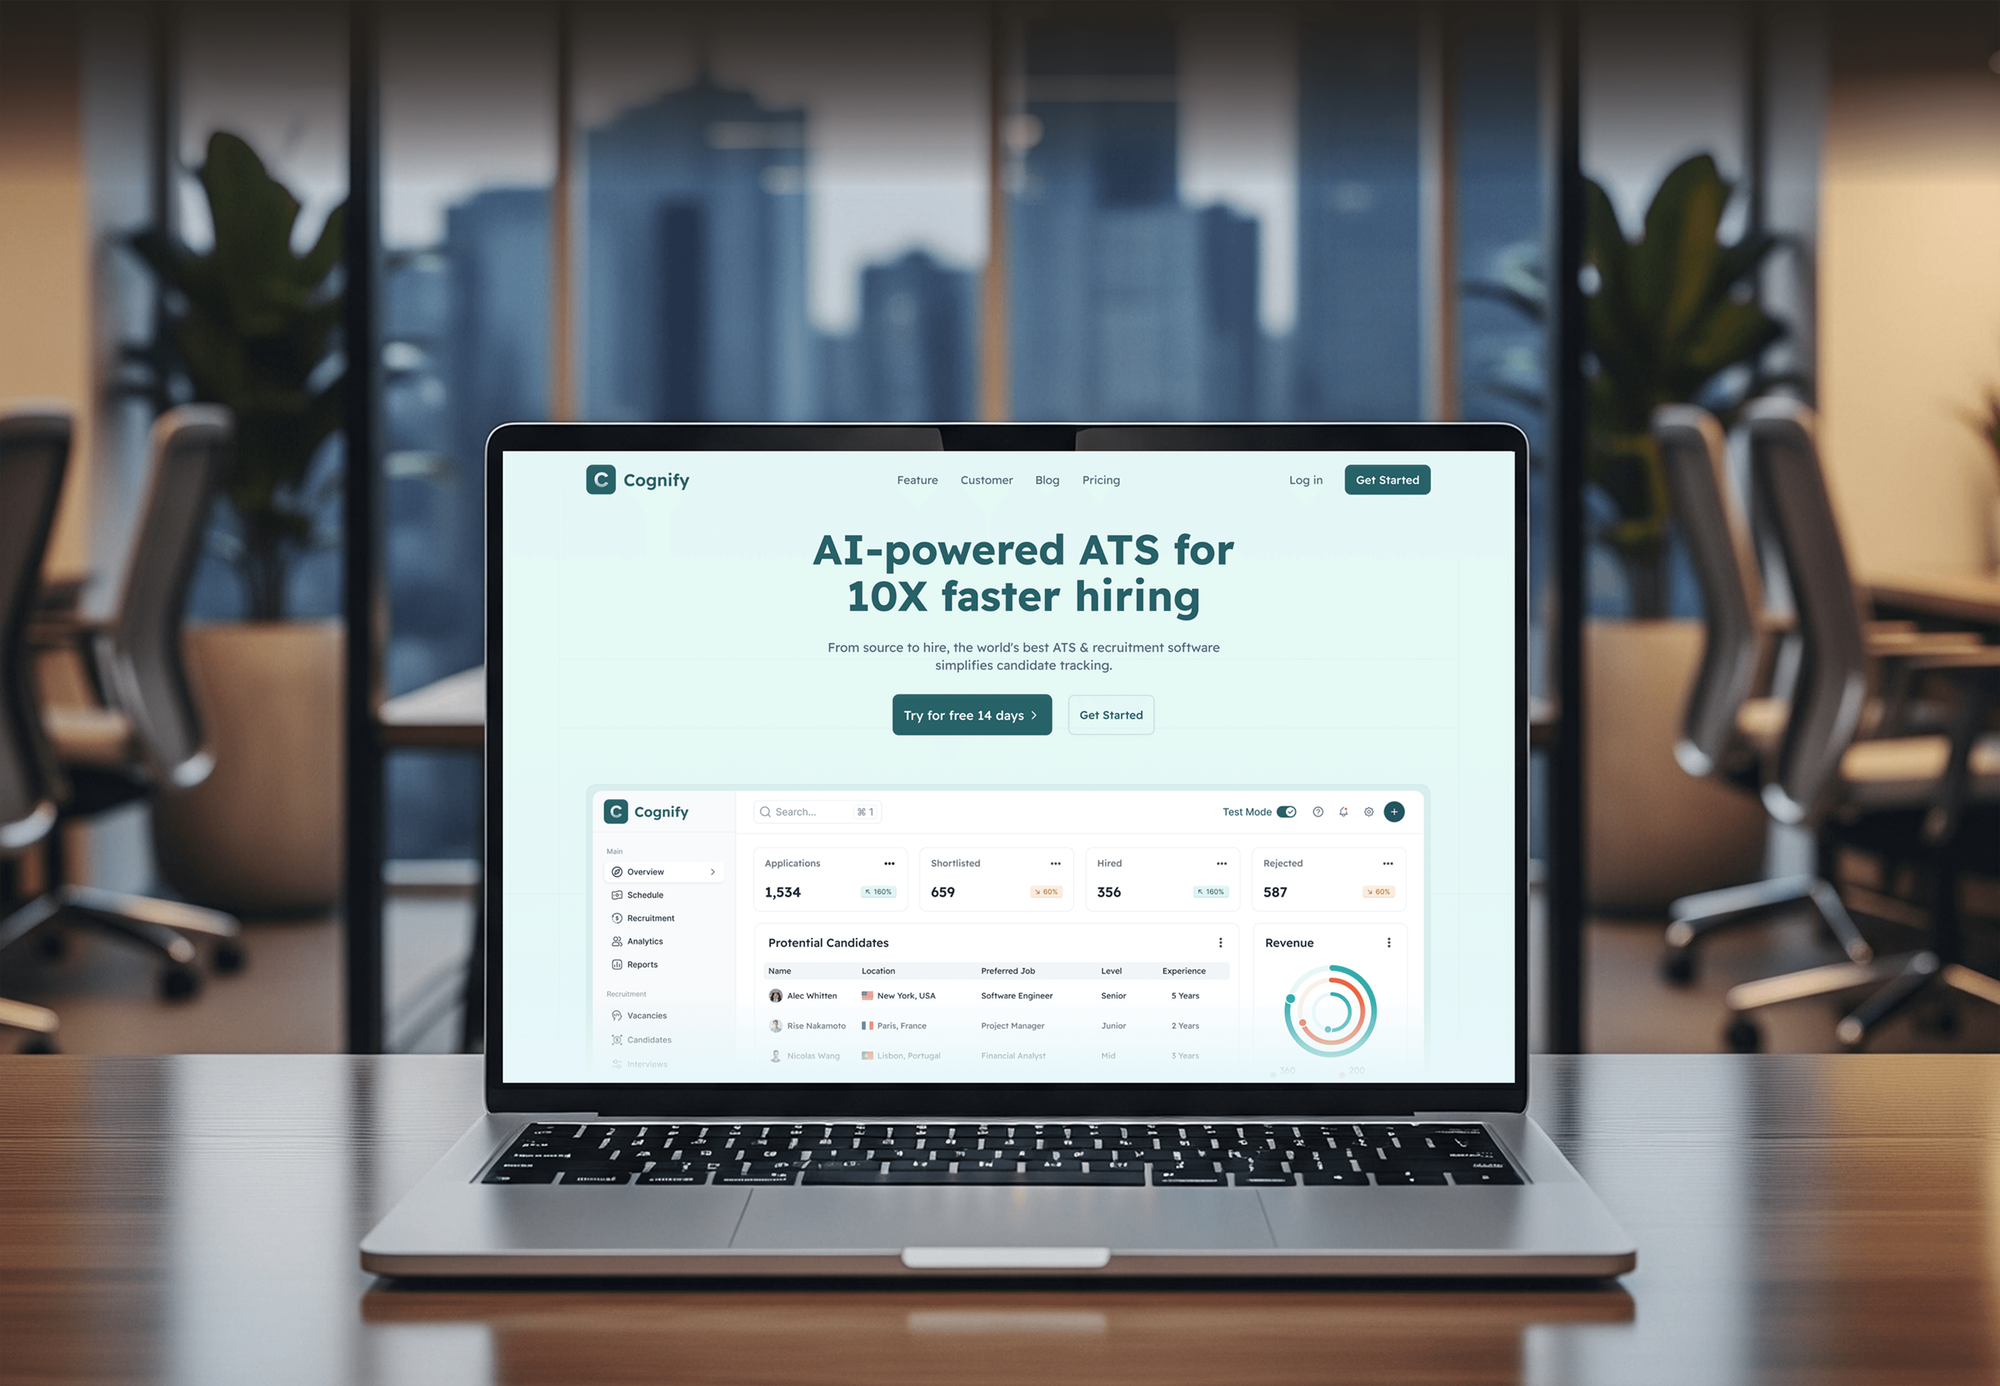
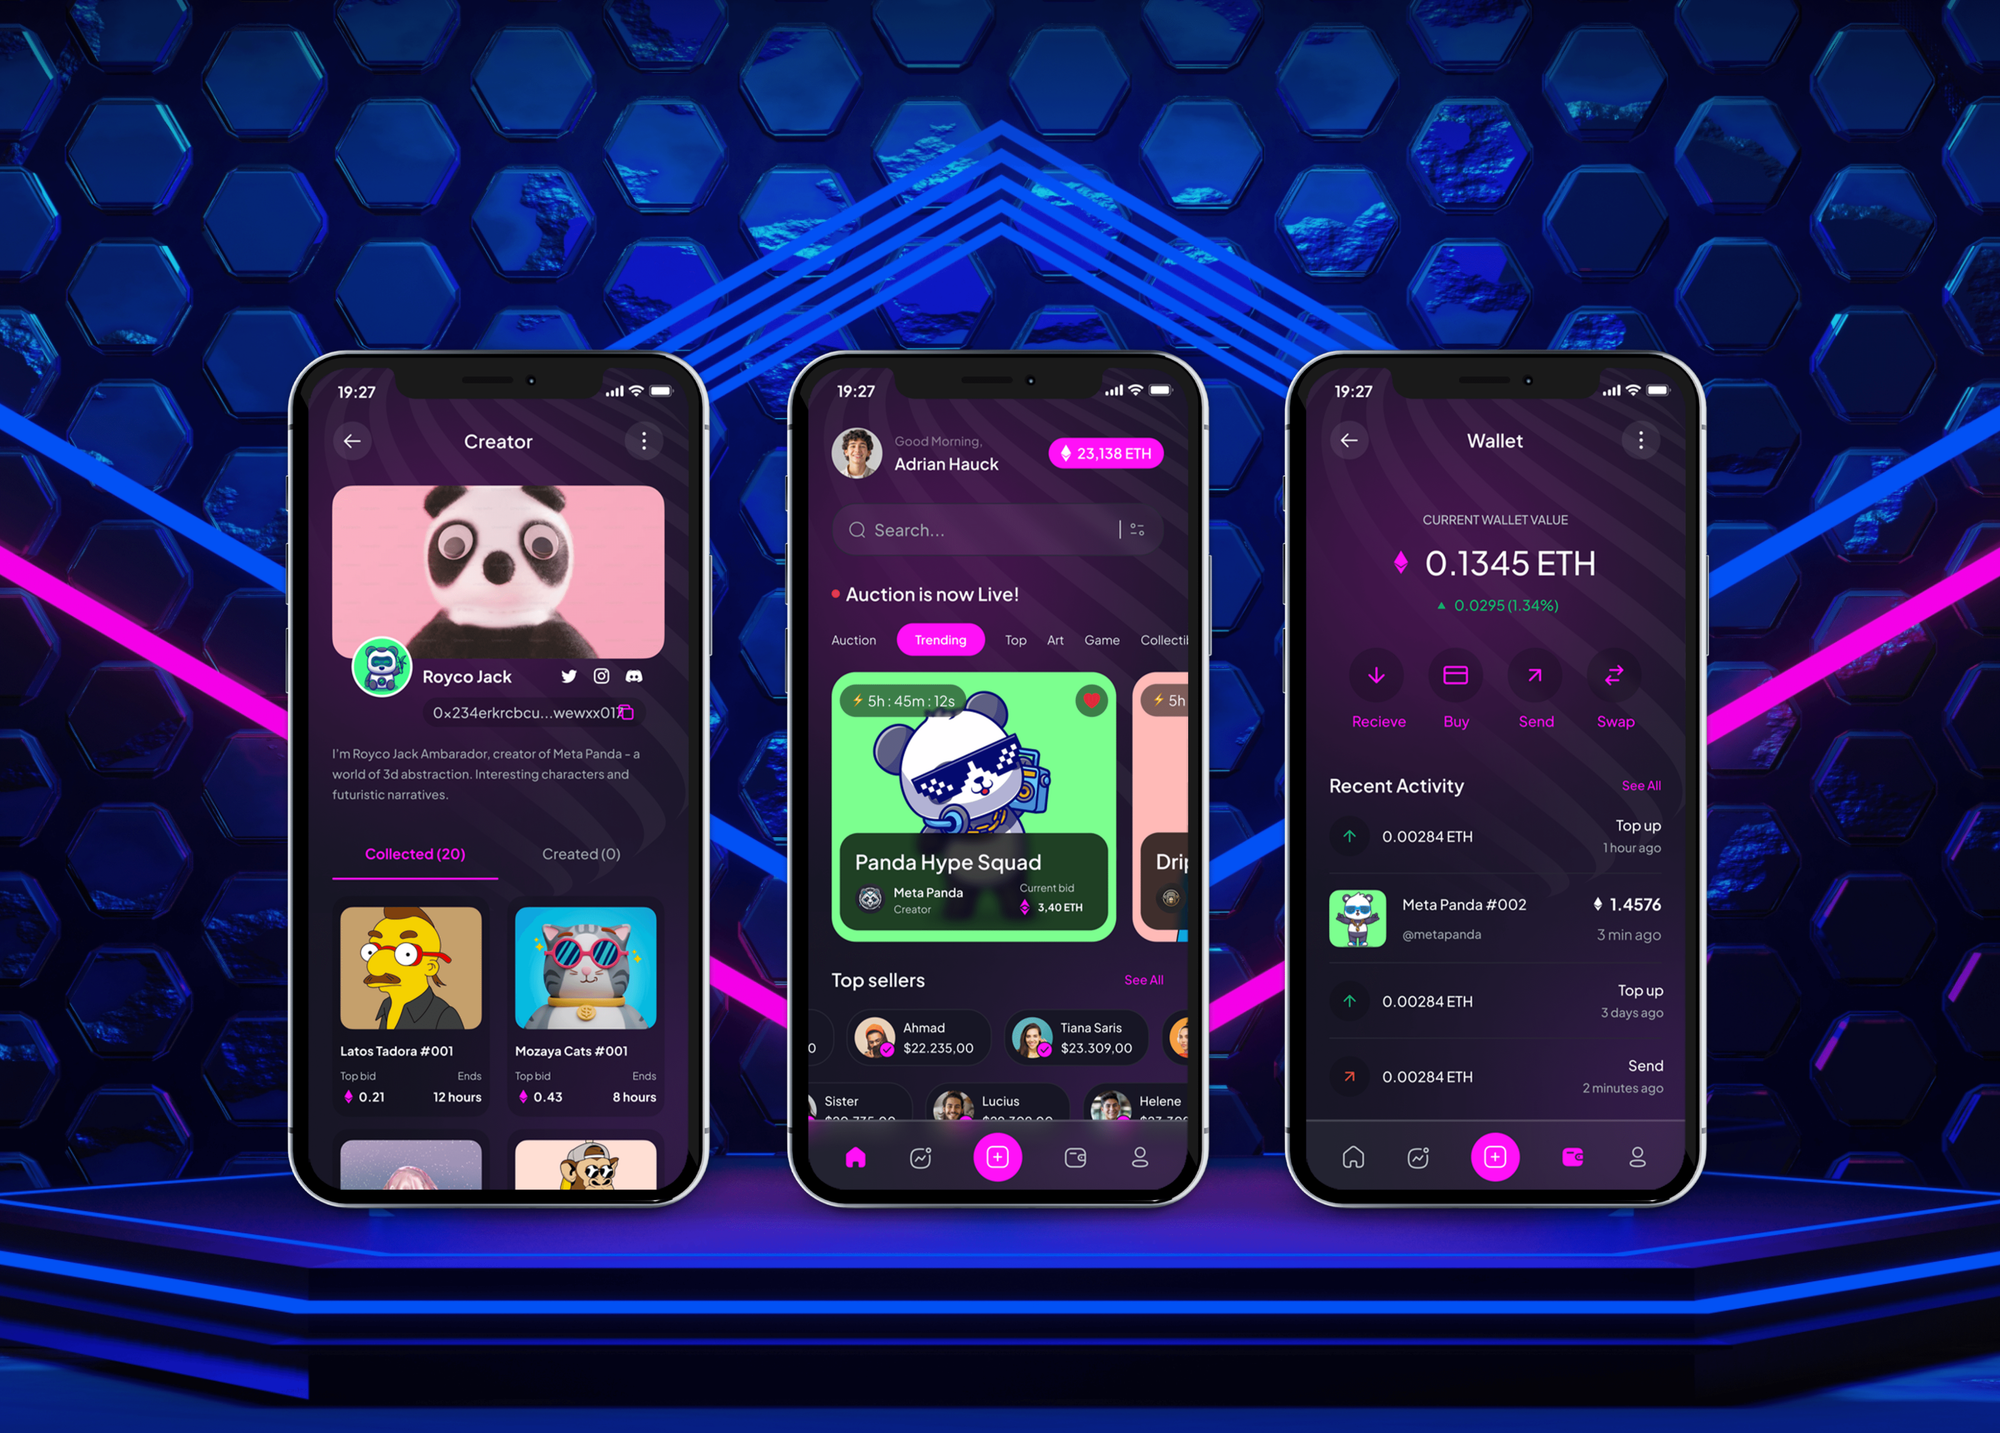
Dashboards and SaaS apps from our portfolio. None was a data engineering engagement, but each runs on the kind of reporting tables and integrations this work produces.
What Our Clients Say
Feedback from teams we have built web apps and dashboards for.
We had a pretty specific idea of what we wanted our website to become, but I wasn’t sure how easily we could explain all of it to a development team. There were quite a few moving parts, and we were working toward a deadline, so I expected a few things to get lost along the way. That never really happened. They understood what we were trying to achieve, kept us updated throughout the process, and got everything ready within the agreed timeline. The final site feels much easier to navigate, works beautifully on mobile, and is noticeably smoother for our customers. It was a huge relief seeing the original idea actually turn into the website we had in mind.
The mobile experience is probably my favourite part of the new site. We had spent a lot of time making sure the desktop version looked right, and the team kept pushing us to think about how everything would actually feel on a phone too. They were right. The navigation is clean, the interactions feel natural, and everything we’ve tested so far works exactly as it should. They also went through the links, forms, integrations, and other details more than once before launch, which I really appreciated. And even after going live, we could still reach out when something came up. The whole process felt friendly, organised, and surprisingly straightforward.
What I appreciate most is that the website is actually easy for us to manage now. We can update content ourselves instead of sending a developer a message every time we need to change something small. They also paid attention to the technical SEO side, which mattered to us because we didn’t want a new website to create problems for the traffic we already had. I’ve probably asked more questions than I should have since launch, but every question has been handled patiently and without any fuss. The team is easy to work with, they explain things clearly, and when we need something changed, they focus on getting it done rather than making the process complicated.
1,250+
Projects shipped
10+
Years of experience
Top 3%
Upwork Top Rated Plus
5 stars
Average review score

Want results like these?
Tell us what you are building. You get a reply within 24 hours on business days, then a written estimate.
Work Culture
Pipelines fail overnight and at quarter-end. These habits keep your numbers right, your warehouse costs visible, and your team able to run things without us.
We check whether a managed connector or your BI tool's own import already does the job. If one does, we'll tell you before we quote.
Every pipeline and dbt model goes through a pull request, review, and CI checks. Broken SQL gets caught in review, not in Monday's dashboard.
We load raw data first and transform it inside the warehouse. When a business rule changes, we rebuild the table from history instead of losing it.
We set auto-suspend, partitioning, and query limits during setup, then show you where the spend goes. Your bill stays predictable when a dashboard starts scanning full tables.
Sensitive columns such as emails and salaries get masked or limited by role. Analysts see what they need, and personal data stays out of shared extracts.
Code, infrastructure, and warehouse accounts sit in your company's name from the first commit. You can switch providers or hire in-house without rebuilding anything.
Overview
DeveloperLook provides data engineering services and solutions for teams whose reports disagree. We build ingestion pipelines, a cloud warehouse, tested dbt models, and Airflow orchestration with failure alerts. Projects start at $1,400, take 3 to 14 weeks, and the code and accounts stay yours.
DEVELOPERLOOK
Project facts · Data Engineering Services
Reviewed 8 Oct 2026 by Saimul Islam
Good fit
Startups outgrowing spreadsheet reporting
Your founders export Stripe, HubSpot, and product data into Google Sheets every Monday, and the totals never match the board deck.
Teams with a warehouse nobody trusts
You bought Snowflake or BigQuery last year, but half the tables are stale, and analysts rebuild the same joins in every dashboard.
SaaS companies building data features
Your product needs usage data in customer-facing reports, so the pipelines and data models must be built like production code, not one-off scripts.
Operations teams on legacy databases
Your ERP and order system run on SQL Server or MySQL, and you need nightly loads into a warehouse without slowing production.
Agencies selling analytics to clients
Your agency sells reporting and needs data engineering consulting services behind the scenes for pipelines you can't staff in-house.
Not a fit
One-time database move
You need to move one database to a new system once, with no ongoing pipelines. Our Data Migration Services page covers that scope at a lower starting price.
Clean data, need dashboards
Your warehouse is already clean and trusted, and you only need reports on top. Our Power BI Consulting and Data Visualization Services pages fit better.
Two sources, small budget
You have two sources and a budget under $1,400. A managed ELT tool feeding a spreadsheet may cover it, and we'll tell you before we quote.
Sub-second streaming at scale
You run trading or IoT telemetry that needs sub-second streaming at very high volume. A specialist streaming team with its own on-call rotation suits that better.
Not sure we're the right fit?
Book a free call or message us. We'll tell you honestly whether we're the right team.
Pricing
These are starting points in USD. Your final price depends on the number of sources, how much history needs backfilling, and how fresh the data must be, and you get a fixed proposal after a free data source review.
For teams that need 2 or 3 sources loaded into one warehouse on a daily schedule.
$1,400one-time, USD
For companies that need several sources modeled into tested, report-ready tables.
$4,200one-time, USD
For product and data teams that need near real-time data and production-grade operations.
$8,900one-time, USD
For Agencies
You own the client relationship. We supply the data engineering: ingestion, warehouse modeling, and orchestration behind the dashboards you sell. Fixed quotes protect your margin, and documented dbt projects make the handover to your client's team simple.
White label: your client only ever sees your brand
Send the client's systems, reporting goals, and any warehouse they already pay for.
You get a source map, a data model, and a fixed quote with a launch date.
Tested pipelines and documentation delivered under your agency's brand, ready for client reports.
Your brand on every deliverable, and no client contact unless you ask.
Every source and data model priced upfront, so your margin holds.
We work in Snowflake, BigQuery, Redshift, and PostgreSQL, whatever your client runs.
Data dictionaries and runbooks your client's analysts can follow without us.
The Right Technology for Your Project
We use the warehouse you already pay for where it fits, open-source dbt and Airflow for transforms and scheduling, and your own cloud account.
 PostgreSQL
 MySQL
 Salesforce
 HubSpot
 Stripe
 Shopify
 Python
 AWS
 Google Cloud
 Microsoft Azure
 Docker
FAQ
Straight answers on data engineering costs, ETL and dbt, Airflow, and choosing the right partner.
Saimul IslamFounder & CEO, DeveloperLookStill have questions?
Send a message or book a call with the team.
Data engineering is the work of collecting, cleaning, and modeling data so people and software can use it. It covers pipelines that pull from apps and databases, a warehouse that stores the history, and transformations that turn raw rows into tables like orders, customers, and revenue. Done well, every report reads from the same tested tables.
A data engineer builds and runs the systems that move data from where it's created to where it's analyzed. Day to day, that means writing ingestion jobs, SQL and Python transformations, tests, and schedules. They also fix broken loads, watch warehouse costs, and agree with analysts on how each table should be modeled.
Our data engineering projects start at $1,400 for up to 3 sources loaded into one warehouse with dbt models and failure alerts. An analytics platform with up to 8 sources and Airflow starts at $4,200. A full data platform with change data capture starts at $8,900. Warehouse and tool subscriptions stay on your own accounts.
A first pipeline usually takes 3 to 5 weeks, and a full data platform takes 8 to 14 weeks. Messy source systems, long historical backfills, and access approvals add the most time, so the free source review sets the real schedule. We ship sources in order of business value, so early reports don't wait for the last connector.
ETL stands for extract, transform, load: pulling data from source systems, reshaping it, and writing it to a target. Most modern stacks use ELT instead. They load raw data into the warehouse first and transform it there with SQL. That keeps the raw history, so you can rebuild a table when a business rule changes.
dbt is an open-source tool that turns SQL SELECT statements into tested, documented tables inside your warehouse. Each model can build on others, so dbt works out the run order and draws the lineage between them. We use its tests, such as unique, not null, and accepted values, to catch bad data before it reaches a dashboard.
Apache Airflow is an open-source orchestrator that schedules and monitors pipelines written as Python DAGs (directed acyclic graphs). It runs tasks in order, retries failures, and keeps a history of every run. We use it, or a managed version such as Amazon MWAA or Google Cloud Composer, when jobs depend on each other.
Choose a partner that treats pipelines like product code, with version control, tests, code review, and alerts. Ask how they handle schema changes, backfills, and warehouse costs, and who owns the code afterward. The best data engineering services companies also ask which decisions the data must support before they pick any tools.
Data engineering as a service means an outside team builds and runs your pipelines instead of you hiring a full-time engineer. With DeveloperLook, you start with a fixed-scope build. After launch, you can keep a monthly support plan for watching loads and adding sources, quoted separately. The code and accounts stay yours either way.
You do. Pipelines, the dbt project, infrastructure code, and warehouse accounts live in your company's GitHub and cloud accounts from day one. At handover, you get a runbook for failed loads, a data dictionary, and 30 to 90 days of support. A careful data engineering services company documents everything, so your next hire can take over.
Saimul IslamFounder & CEO, DeveloperLookStill have questions?
Send a message or book a call with the team.
Free 30-min callGoogle Meet
Book a call
In 30 minutes on Google Meet we walk you through how we would build it, how long it takes and what it costs. Then you get a written estimate.
Calendar not showing? Book on cal.com or send a brief.